I am a PhD candidate in the CRUISE Lab at UNSW Sydney, supervised by Prof. Flora Salim, Prof. Hao Xue, and Prof. Imran Razzak. My research spans trustworthy machine learning and LLM personalization, focusing on accuracy–fairness alignment, joint robustness and individual fairness, and constraint-based personalization to build reliable AI systems for positive social impact.
Prior to joining UNSW, I completed my master’s degree at the State Key Laboratory of Computer Science, Institute of Software, Chinese Academy of Sciences, advised by Profs. Peng Wu and Jian Zhang. Following graduation, I worked as a research assistant with Prof. Yi Zeng at the Institute of Automation, Chinese Academy of Sciences, and subsequently with Prof. Xingjun Ma in the FVL Lab at Fudan University.
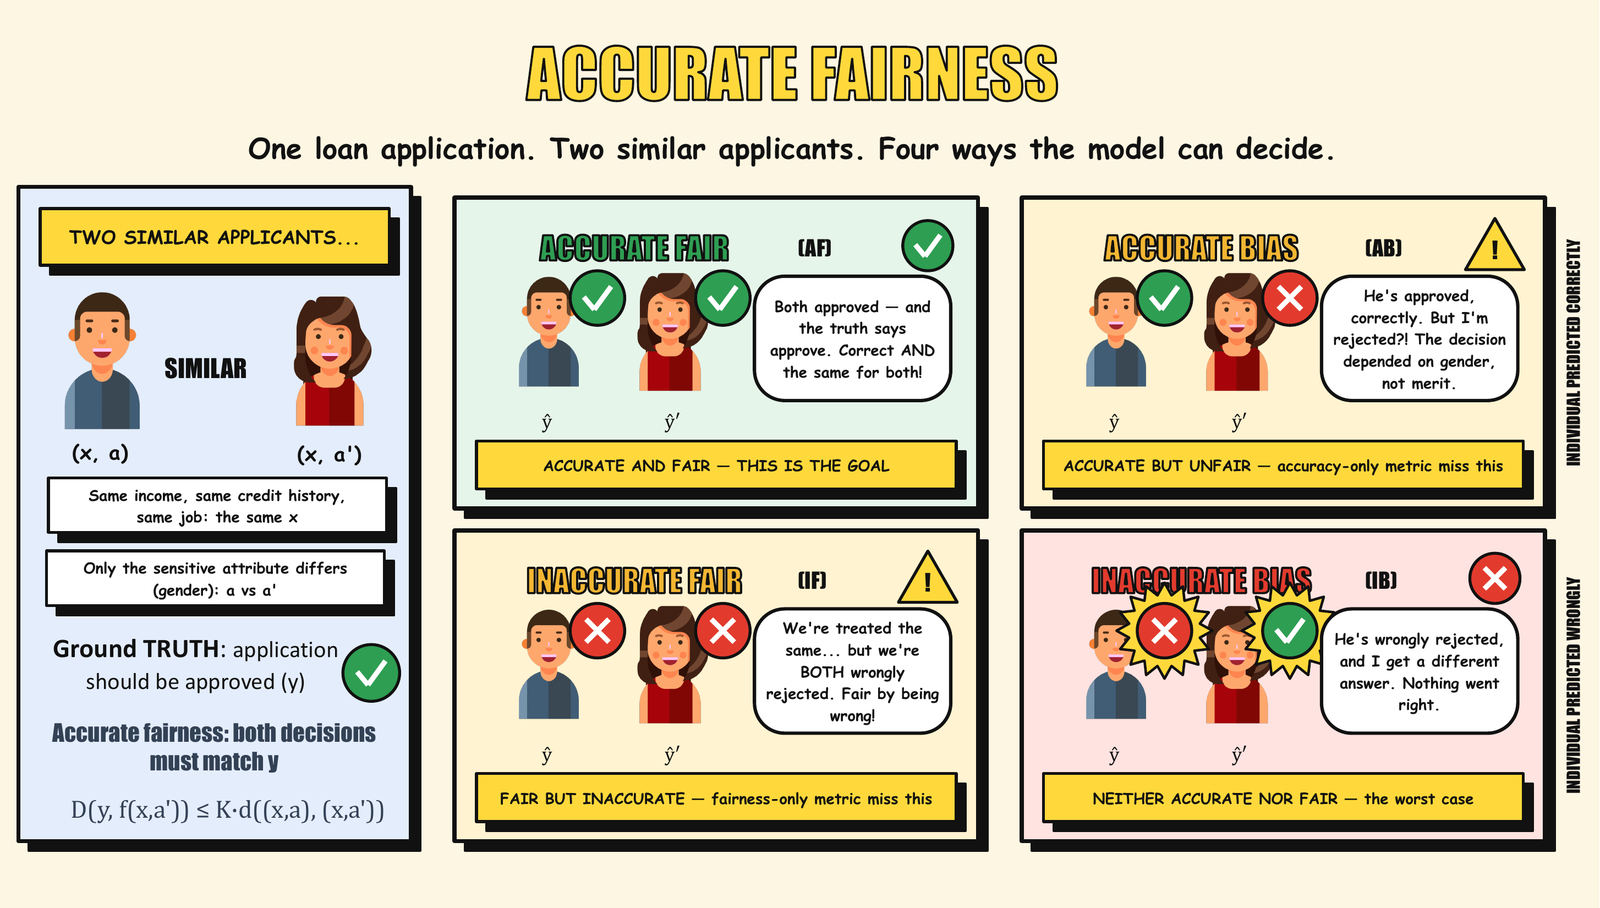
A fair model without accuracy is impractical; an accurate model without fairness is untrustworthy. We introduce accurate fairness—aligning the treatment of similar individuals with ground-truth targets—optimized through a Siamese in-processing scheme and measured via a fairness confusion matrix.
Read the AAAI 2023 paper
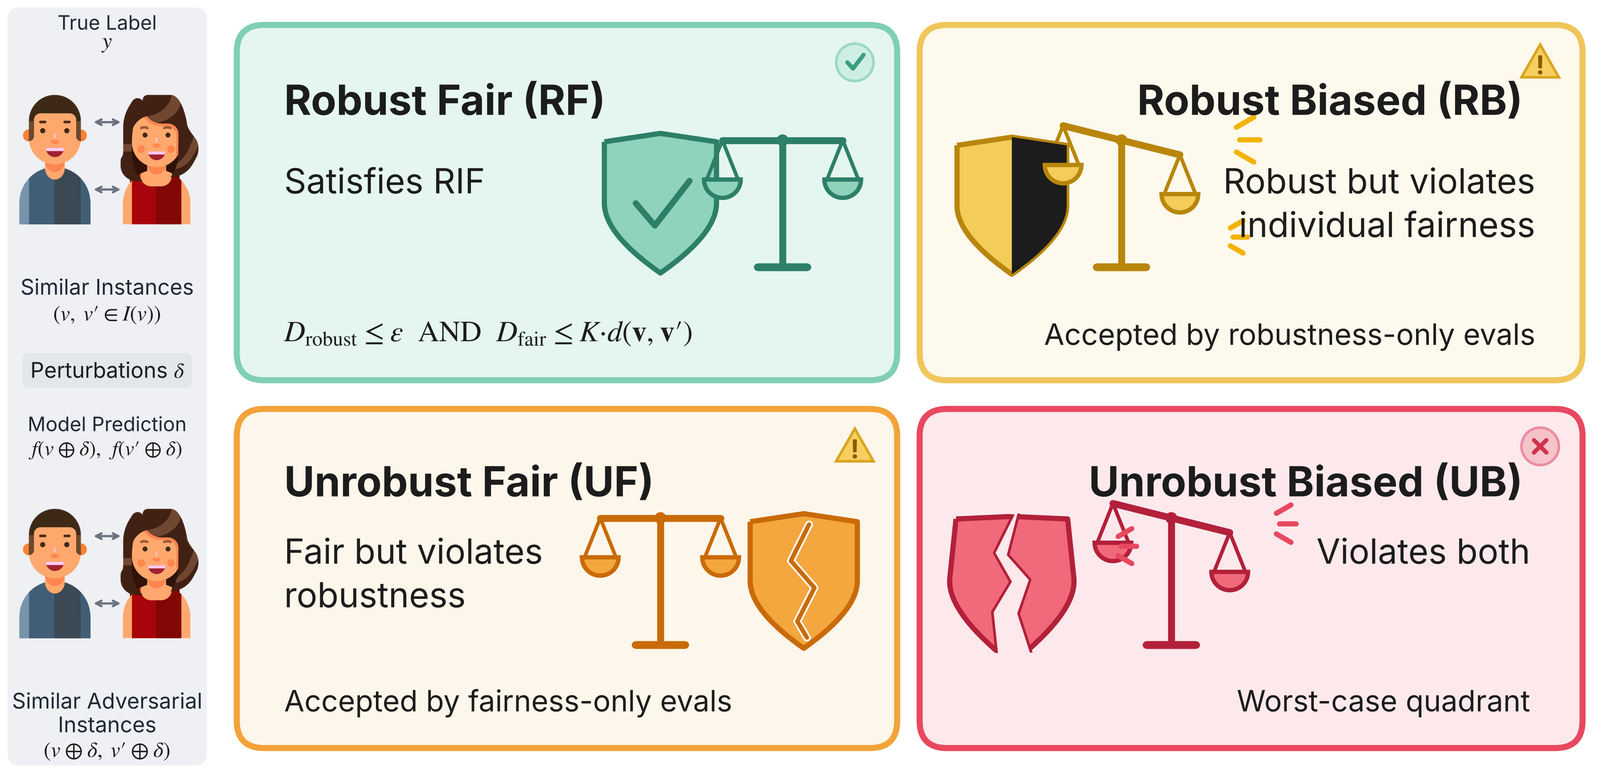
Adversarial edits can simultaneously compromise neural network reliability and equity. A robust model without fairness is biased; a fair model without robustness is fragile. We introduce Robust Individual Fairness (RIF)—aligning invariance across similar individuals with robustness against semantic perturbations—and develop RIFair, a black-box attack using decoupled perturbations to reveal failure modes missed by single-axis evaluations.
Read the KDD 2026 paper
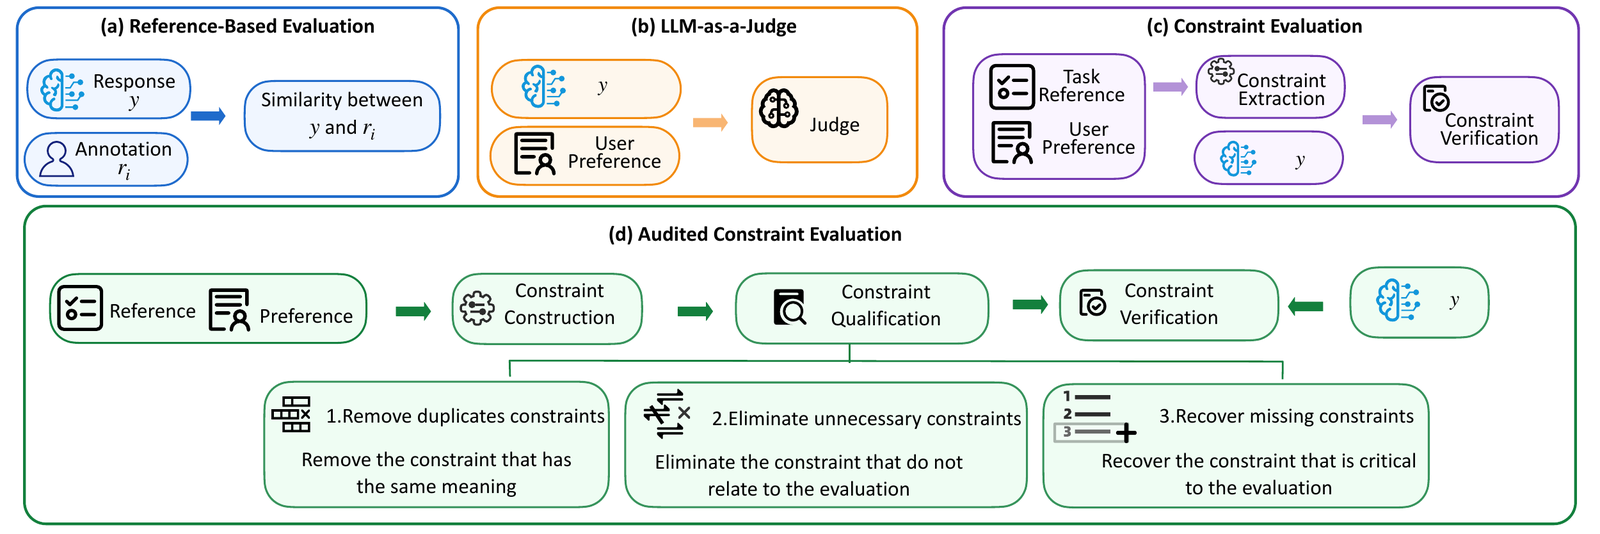
Over-constraining personalization evaluation falsely rejects valid outputs; under-constraining it falsely accepts misaligned ones. We introduce ConQual-Audit, an audit-based, constraint-driven framework that extracts semantic constraints from profiles and references, qualifies them through pruning and recovery, and verifies candidate responses via natural language inference to achieve reliable evaluation.
Read the preprint and get the codeSiamese fairness in-processing and the fairness confusion matrix. Pre-trained baseline and Siamese models for Adult, German Credit, COMPAS and Ctrip, so the evaluation reproduces without training.
Black-box adversarial framework for robust individual fairness in NLP: Generate–Filter perturbation space, query-based token ranking, decoupled search for RB / UF / UB pairs, and adversarial retraining.
Audit-based evaluation of LLM personalization: construct constraints from the user profile and task reference, qualify them by pruning and recovery, verify responses with NLI. Benchmarks on PrefEval and LaMP.